Category: Business Improvement and Transformation

Business Improvement and Transformation

  • 5 Questions to Ask About Data Quality

    Data quality refers to the accuracy, completeness, consistency, and reliability of data. In the modern era of data-driven decision-making, organizations heavily rely on data to gain insights, make informed choices, and drive business strategies. Data quality ensures that the data used for analysis and decision-making is trustworthy, enabling organizations to have confidence in the results obtained from data-driven processes.

    The Pros of Data Quality

    1. Informed Decision-Making: High data quality leads to reliable insights, enabling better decision-making at all levels of the organization.
    2. Business Performance: Accurate data improves business performance by identifying areas of improvement and growth opportunities.
    3. Customer Trust: High data quality fosters trust with customers, as it ensures that their information is treated with care and accuracy.
    4. Compliance and Regulation: Data quality is crucial for organizations that need to comply with industry regulations and data protection laws.
    5. Process Efficiency: Reliable data minimizes errors and rework, leading to improved operational efficiency.

    The Cons of Data Quality

    1. Data Complexity: Ensuring data quality can be challenging due to the diverse sources, formats, and structures of data.
    2. Data Cleaning and Validation: Data cleaning and validation can be time-consuming and resource-intensive.
    3. Data Integration Challenges: Data quality may suffer during the integration of data from different systems.
    4. Data Decay: Data quality can degrade over time if not continuously monitored and maintained.
    5. Impact on Decision-Making: Poor data quality can lead to inaccurate insights and flawed decision-making.

    Intriguing Questions about Data Quality

    1. Who: Who within the organization is responsible for maintaining and monitoring data quality – data analysts, data stewards, or cross-functional teams?
    2. What: What are the key metrics and indicators used to measure data quality in different industries?
    3. Where: Where do we see the most significant impact of data quality – in finance, healthcare, or e-commerce?
    4. When: When is the optimal time to invest in data quality initiatives – during data collection, data processing, or data analysis?
    5. Why: Why is data quality a critical factor in the success of data-driven organizations and their ability to stay competitive?

    Conclusion

    Data quality is a vital component of any data-driven organization, as it ensures that decisions are based on accurate and reliable information. While it may present challenges due to data complexity and data decay, the benefits of informed decision-making, improved business performance, and customer trust make investing in data quality initiatives worthwhile. By prioritizing data quality and implementing robust data cleaning and validation processes, organizations can unleash the true potential of their data assets, gaining a competitive advantage in today’s data-driven business landscape.
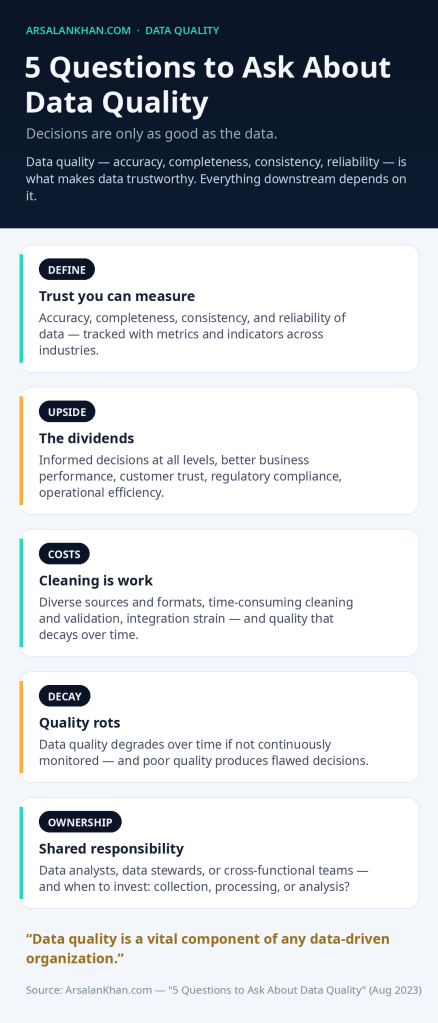
    Infographic: 5 Questions to Ask About Data Quality

  • 5 Questions to Ask About Data Preparation

    Data preparation is a crucial step in the data analysis process that involves cleaning, transforming, and organizing raw data into a structured and usable format. It is often considered the most time-consuming and labor-intensive phase of data analysis, as the quality of insights and results heavily relies on the accuracy and completeness of the prepared data.

    Key Steps in Data Preparation

    1. Data Collection: Raw data is collected from various sources, such as databases, spreadsheets, sensors, social media, or web scraping.
    2. Data Cleaning: Data is thoroughly examined to identify and rectify errors, inconsistencies, missing values, and outliers that could skew the analysis.
    3. Data Transformation: Data is transformed to align with the analysis requirements. This may involve standardization, normalization, encoding categorical variables, and feature engineering.
    4. Data Integration: If multiple data sources are used, data from different sources is integrated and merged into a unified dataset.
    5. Data Reduction: For large datasets, data reduction techniques, such as sampling or feature selection, may be employed to improve efficiency without sacrificing meaningful insights.
    6. Data Formatting: The data is formatted to ensure uniformity and compatibility with the chosen analysis methods and tools.

    The Pros of Data Preparation

    1. Improved Data Quality: Data preparation ensures that the data used for analysis is accurate, complete, and free from errors.
    2. Enhanced Analysis Accuracy: Clean and organized data leads to more reliable and accurate analysis results.
    3. Efficient Data Processing: Prepared data allows for faster and more efficient data analysis.
    4. Better Data Insights: Data preparation helps uncover meaningful patterns and relationships in the data.
    5. Data Integration: Data preparation enables the integration of diverse data sources, providing a comprehensive view for analysis.

    The Cons of Data Preparation

    1. Time-Consuming: Data preparation can be time-consuming, especially when dealing with large and complex datasets.
    2. Subjectivity: Some data cleaning and transformation decisions may involve subjective judgment, potentially introducing bias.
    3. Data Loss: In the process of cleaning and reducing data, some valuable information may be lost.
    4. Data Privacy: Data preparation involves handling sensitive information, requiring careful attention to data privacy and security.
    5. Complexity: Preparing data from multiple sources or in various formats may require specialized skills and knowledge.

    Intriguing Questions about Data Preparation

    1. Who: Who are the key stakeholders involved in the data preparation process within organizations, and what roles do they play?
    2. What: What are some common challenges and best practices in data cleaning and transformation?
    3. Where: Where do organizations often encounter data preparation bottlenecks, and how can these challenges be overcome?
    4. When: When is the best time to perform data preparation in the overall data analysis workflow?
    5. Why: Why is data preparation considered a critical step in ensuring the accuracy and reliability of data analysis results?

    Conclusion

    Data preparation is an essential foundational step in the data analysis process. By cleaning, transforming, and organizing raw data, data preparation ensures that the subsequent analysis is accurate, reliable, and capable of generating meaningful insights. While it requires time and expertise, investing effort in data preparation is crucial for obtaining valuable and actionable information from complex datasets. As data analysis continues to play a central role in decision-making across industries, the significance of data preparation in obtaining reliable and trustworthy results is likely to grow further.

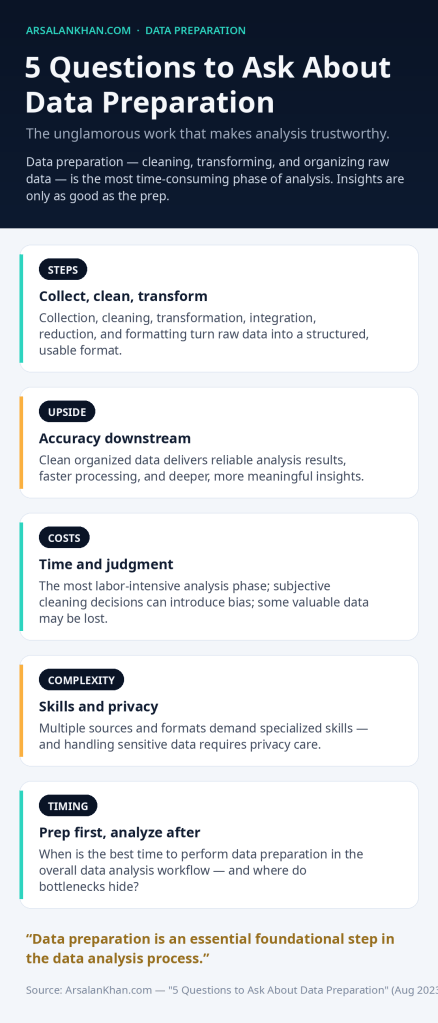
    Infographic: 5 Questions to Ask About Data Preparation
  • 5 Questions to Ask About Data Governance

    Data governance refers to the establishment of rules, policies, and processes to ensure the proper management, usage, and protection of an organization’s data assets. It involves defining responsibilities, roles, and guidelines for data management, ensuring data quality, compliance with regulations, and promoting data-driven decision-making. Data governance is essential for organizations that rely on data to drive business strategies, as it establishes a strong foundation for data management and ensures that data is treated as a valuable strategic asset.

    The Pros of Data Governance

    1. Data Quality and Consistency: Data governance promotes data quality initiatives, ensuring that data is accurate, reliable, and consistent.
    2. Data Security and Privacy: Implementing data governance measures enhances data security and privacy, safeguarding sensitive information from unauthorized access.
    3. Compliance and Regulatory Adherence: Data governance ensures that data practices comply with relevant laws, regulations, and industry standards.
    4. Data Accountability: Data governance assigns clear roles and responsibilities for data management, promoting accountability within the organization.
    5. Informed Decision-Making: Data governance enables data-driven decision-making by providing reliable and trusted data to decision-makers.

    The Cons of Data Governance

    1. Complexity and Implementation Challenges: Establishing a comprehensive data governance framework can be complex and may face implementation challenges.
    2. Resistance to Change: Implementing data governance may face resistance from stakeholders accustomed to traditional data practices.
    3. Resource and Time Intensive: Building and maintaining a data governance program requires significant resources and ongoing efforts.
    4. Balancing Flexibility and Control: Striking a balance between data control and providing flexibility for data users can be challenging.
    5. Cross-Organizational Collaboration: Effective data governance requires collaboration across departments, which may pose challenges in large organizations.

    Intriguing Questions about Data Governance

    1. Who: Who are the key individuals or departments responsible for driving data governance initiatives within organizations – CDOs, data stewards, or cross-functional teams?
    2. What: What are the best practices and methodologies for establishing and maintaining a successful data governance program?
    3. Where: Where do we see the most significant impact of data governance – in industries like finance, healthcare, or government?
    4. When: When is the optimal time for organizations to invest in data governance – during data acquisition, data storage, or data analysis stages?
    5. Why: Why is data governance considered a critical factor in organizations’ success in the era of big data and data-driven strategies?

    Conclusion

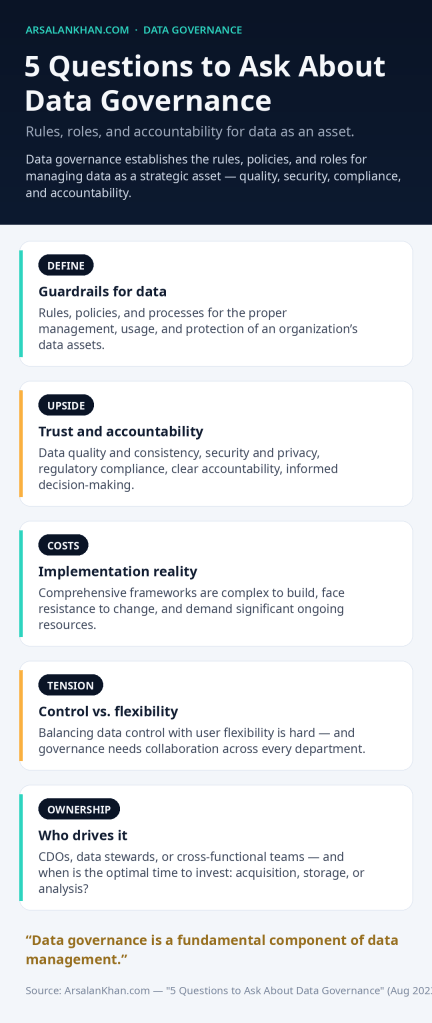
    Data governance is a fundamental component of data management, establishing rules, policies, and guidelines to ensure data quality, security, and compliance. While it may face challenges in implementation and require substantial resources, the benefits of improved data quality, enhanced decision-making, and data security make it a strategic investment for organizations. By embracing data governance as a core principle, organizations can build a strong foundation for data management, harness the full potential of their data assets, and stay competitive in an increasingly data-driven business landscape.

    Infographic: 5 Questions to Ask About Data Governance

  • 5 Questions to Ask About Open Data

    Open data refers to the concept of making data freely available to the public, without any restrictions or limitations on its use, reuse, and distribution. The goal of open data initiatives is to promote transparency, foster collaboration, and drive innovation by allowing individuals, businesses, researchers, and governments to access and utilize data for various purposes.

    Characteristics of Open Data

    1. Accessibility: Open data is easily accessible to anyone, typically through online platforms or data portals.
    2. Licensing: Open data is usually accompanied by open licenses that explicitly grant permission for reuse and redistribution.
    3. Formats: Data is provided in machine-readable formats, enabling easy analysis and integration into various applications.
    4. Timeliness: Open data is often made available in near real-time to ensure it remains relevant and up-to-date.
    5. Diversity: Open data encompasses a wide range of information, including government statistics, scientific research, environmental data, and more.

    The Pros of Open Data

    1. Transparency: Open data promotes transparency and accountability by allowing citizens to access information on government activities and public services.
    2. Innovation: Open data fuels innovation by providing a rich source of information for researchers, entrepreneurs, and developers to build new applications and services.
    3. Collaboration: Open data encourages collaboration between public and private sectors, academia, and civil society, leading to data-driven insights and solutions.
    4. Economic Growth: Open data can stimulate economic growth by fostering new business opportunities and market developments.
    5. Empowerment: Open data empowers individuals with information, enabling them to make informed decisions and participate in civic activities.

    The Cons of Open Data

    1. Privacy Concerns: The release of certain data may raise privacy concerns, especially when it includes sensitive or personally identifiable information.
    2. Data Quality: Ensuring the quality and accuracy of open data can be challenging, potentially leading to misinformation.
    3. Data Bias: Open data may reflect biases present in the source data, affecting the fairness and equity of analyses and applications.
    4. Data Governance: Managing and governing open data requires resources and clear policies to maintain its integrity and relevance.
    5. Security Risks: Making data openly available may expose it to potential security risks and unauthorized access.

    Intriguing Questions about Open Data

    1. Who: Who are the key stakeholders in open data initiatives – governments, researchers, businesses, or the general public?
    2. What: What are some of the most impactful use cases of open data in different industries or social sectors?
    3. Where: Where has open data made the most significant impact – in developing countries, urban planning, healthcare, or disaster response?
    4. When: When should organizations or governments decide to make data openly available, and what factors influence this decision?
    5. Why: Why is open data considered a critical driver of data-driven decision-making and progress in the digital age?

    Conclusion

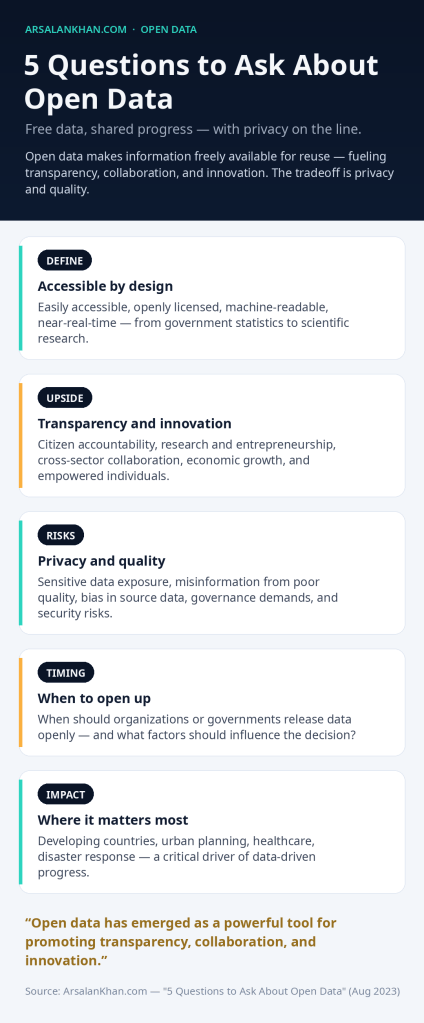
    Open data has emerged as a powerful tool for promoting transparency, collaboration, and innovation. By providing unrestricted access to data, open data initiatives empower individuals and organizations to leverage information for research, problem-solving, and decision-making. While there are challenges concerning privacy, data quality, and governance, the potential benefits of open data in driving economic growth, improving public services, and fostering a data-driven society make it an essential component of the modern data landscape. As open data initiatives continue to evolve and expand, their impact on various sectors and the broader community is likely to grow, ushering in an era of data-driven empowerment and progress.

    Infographic: 5 Questions to Ask About Open Data
  • 5 Questions to Ask About Synthetic Data

    Synthetic data refers to artificially generated data that mimics the statistical properties and characteristics of real data without containing any actual personally identifiable information (PII) or sensitive data. It is created using various statistical and machine learning techniques and can be used as a privacy-preserving alternative for sensitive datasets in research, analysis, and model training.

    How Synthetic Data is Generated

    1. Statistical Methods: Synthetic data can be generated using statistical methods, such as random sampling, probability distributions, and data interpolation.
    2. Machine Learning Techniques: Advanced machine learning algorithms, like Generative Adversarial Networks (GANs) and Variational Autoencoders (VAEs), can create synthetic data that closely resembles the original data distribution.
    3. Preserving Privacy: Synthetic data generation techniques ensure that individual records in the synthetic dataset cannot be linked back to real individuals.

    The Pros of Synthetic Data

    1. Privacy Protection: Synthetic data allows organizations to perform data analysis and share data externally without risking the exposure of sensitive information.
    2. Data Sharing: Researchers and organizations can freely share synthetic datasets without legal or ethical concerns, fostering collaboration.
    3. Cost Savings: Generating synthetic data eliminates the need to manage and secure large volumes of real data, reducing storage and compliance costs.
    4. Data Augmentation: Synthetic data can be used to augment real datasets, boosting the size and diversity of data for better model training.
    5. Preserving Data Utility: High-quality synthetic data retains the statistical patterns and correlations of real data, making it valuable for accurate analysis.

    The Cons of Synthetic Data

    1. Loss of Granularity: Synthetic data may not capture the exact nuances and granular details present in real data.
    2. Model Bias: If the synthetic data is not representative of the entire dataset, it may introduce bias into the analysis or model training.
    3. Complexity in Generation: Generating high-quality synthetic data can be complex and require expertise in statistical and machine learning techniques.
    4. Data Validation: Ensuring the quality and validity of synthetic data is challenging, especially when validating against real-world scenarios.
    5. Limited Applicability: Synthetic data may not be suitable for certain applications that require real-world interactions and scenarios.

    Intriguing Questions about Synthetic Data

    1. Who: Who benefits the most from using synthetic data – data scientists, researchers, or organizations dealing with sensitive data?
    2. What: What are the most innovative techniques for generating synthetic data, and how do they compare in terms of data utility and privacy protection?
    3. Where: Where is the adoption of synthetic data most prominent – in healthcare, finance, or other industries with stringent data privacy regulations?
    4. When: When is synthetic data preferred over other privacy-preserving techniques, like data masking or differential privacy?
    5. Why: Why is synthetic data gaining traction as a privacy solution, and what are the limitations that researchers are currently trying to overcome?

    Conclusion

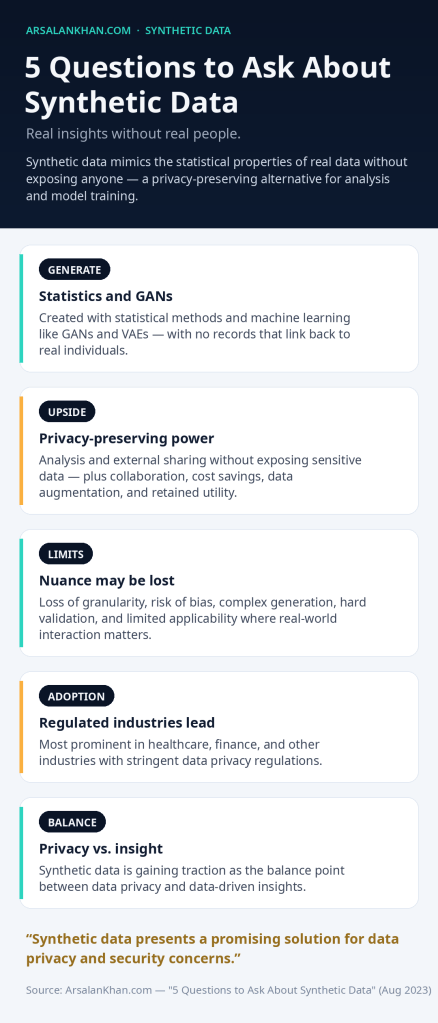
    Synthetic data presents a promising solution for data privacy and security concerns, allowing organizations and researchers to perform analysis and model training without exposing sensitive information. By leveraging statistical and machine learning techniques, synthetic data can retain data utility while ensuring privacy protection. However, careful consideration should be given to its generation process and validation to ensure its accuracy and usefulness in various applications. As synthetic data techniques continue to advance, they will likely play a crucial role in striking a balance between data privacy and data-driven insights in the future.

    Infographic: 5 Questions to Ask About Synthetic Data